Inside Attention, Part 1: The Mechanism
Attention is the engine. The rest of the transformer architecture stabilizes it, organizes it, and makes deep training possible.
What You'll Learn
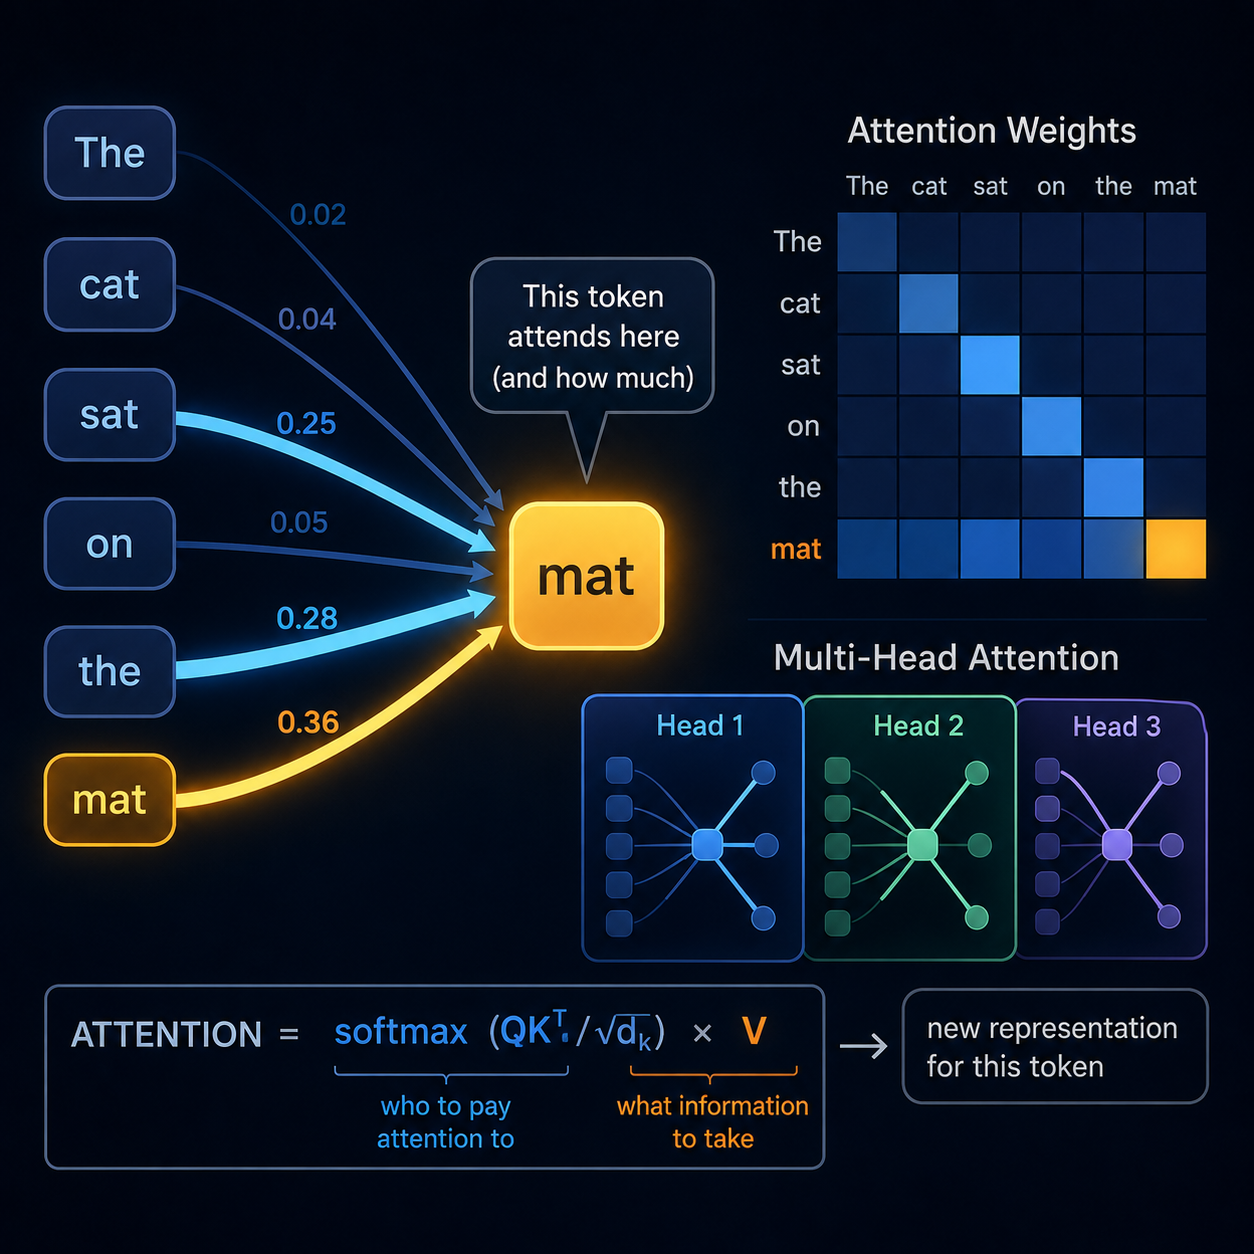
- How queries, keys, and values work together to let tokens exchange information
- Why attention scores are divided by the square root of the key dimension
- How scaling prevents softmax from saturating and preserves useful gradient flow
- Why transformers split attention across multiple heads instead of using one large attention operation
- What researchers have discovered about the specialized roles learned by attention heads
- How induction heads learn a match-and-copy algorithm that helps explain in-context learning